A customer writes: “I was charged twice, and now I can’t log in.”
Before an AI assistant drafts its reply, the application has several decisions to make. Which team should handle the message? How urgent is it? Does it need account verification? Should the system retrieve a billing policy, investigate an access problem, or escalate to a person?
Each judgment could become another call to a generative language model. Multiply those calls across thousands of customers and the cost of deciding what to do becomes a substantial part of the system itself.
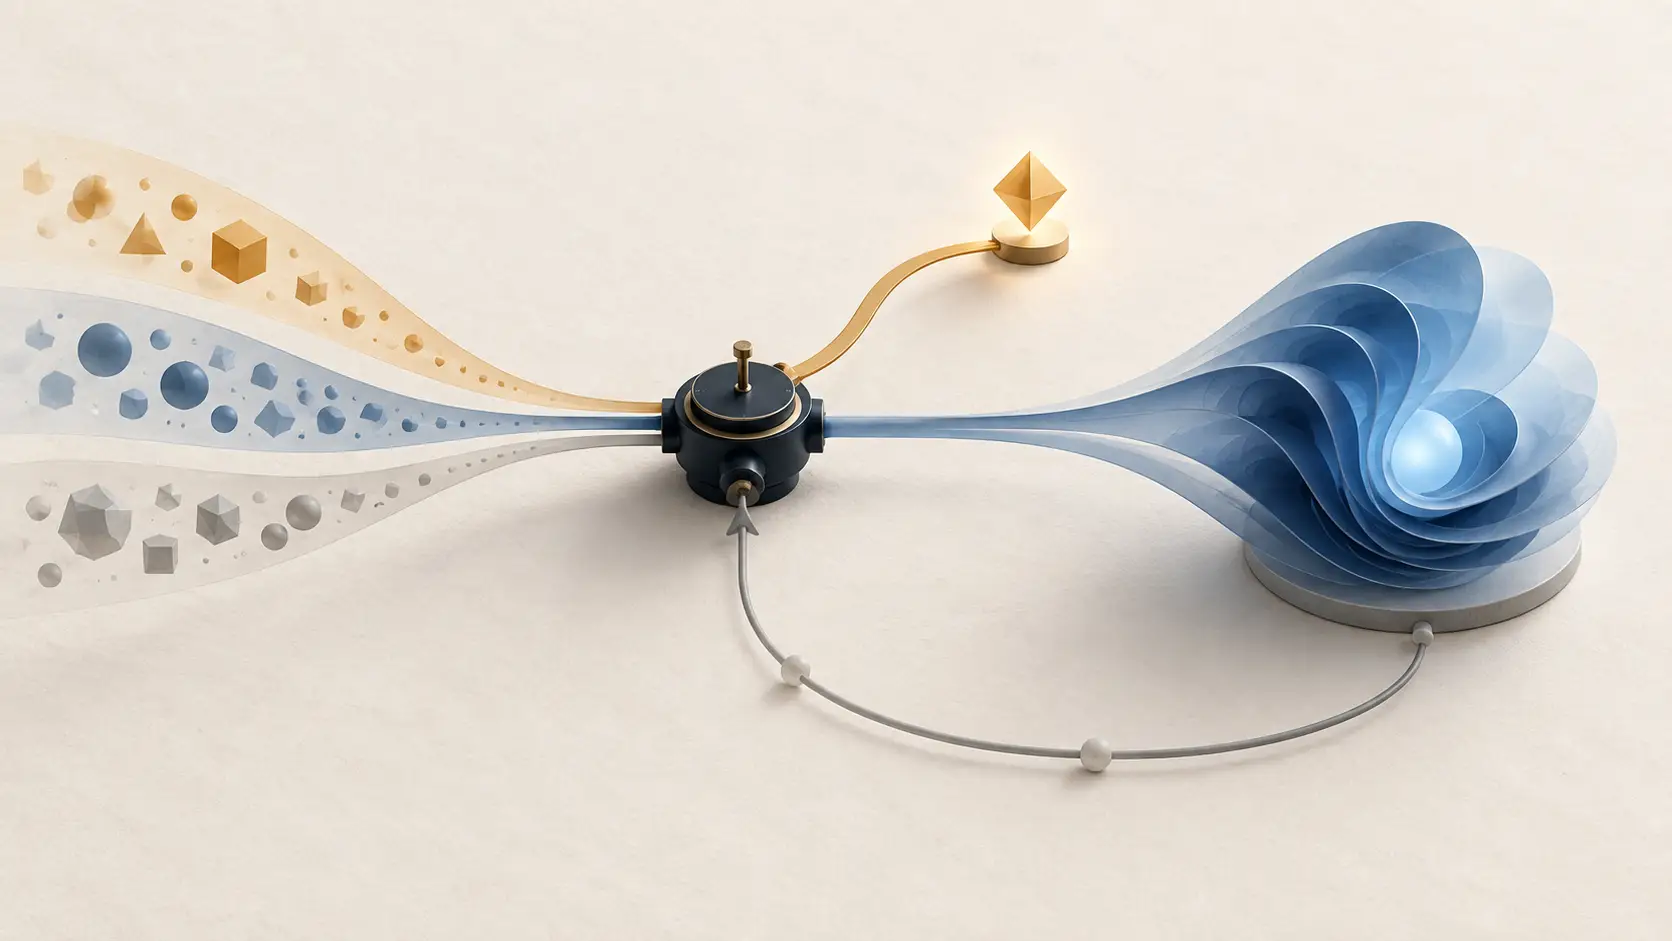
Jev offers a different approach. TypeSafe AI’s decision model takes context and typed questions, then returns choices, scores, and probabilities that software can consume directly. Multiple questions can be evaluated in parallel against shared context. TypeSafe documentation
The prediction at the center of this article is straightforward: Jev will improve, competing decision models will proliferate, and this architecture will become a standard part of generative AI applications. The direction is right because it aligns the work performed by a model with the result the application actually needs.
Giving software a useful form of intelligence
Jev exposes three decision primitives. Choice selects from supplied options. Score evaluates material against defined levels. Noul returns a probability for a yes/no proposition. Choice and Score also provide probability distributions and a separate confidence value. Jev’s output primitives
For the support message, an application could ask about routing, urgency, and refund intent in one request. Code would then combine the answers with account information and business rules. A generative model could write the customer’s reply once the application had established the next step.
That division of work matters. Many operations surrounding generation are classifications, rankings, or checks. Their useful output is a decision that changes program behavior.
Jev makes this relationship explicit. Developers define the available outcomes, the criteria for choosing among them, and the behavior that follows. The model contributes semantic judgment; the surrounding software remains responsible for combining results and executing actions.
This also changes how uncertainty enters an application. TypeSafe’s Reinforcement Learning for Calibrated Decisions, or RLCD, targets decisions whose probabilities reflect outcome frequencies. A well-calibrated probability of 0.8 means that, across comparable predictions assigned that probability, the outcome occurs roughly 80% of the time. It is a statistical property measured over many cases. TypeSafe’s training overview
Useful uncertainty allows software to choose when to proceed, gather more information, or escalate to a stronger model.
What changes relative to a self-attention LLM?
Self-attention lets a Transformer combine information across tokens. Each position computes weighted relationships with other positions, helping the model interpret the sequence in context.
In an autoregressive Transformer, causal masking restricts access to future tokens. Generation produces successive tokens conditioned on the prompt and preceding output. Attention calculations themselves support parallel computation; the generated sequence retains dependencies between its tokens. Attention Is All You Need
The architectural opportunity is to change the prediction target and output process. A system asked to select a label or estimate a proposition’s probability can return that result directly, avoiding the generation of an answer sequence.
Transformers already support classification and other language-understanding tasks. BERT demonstrated that pretrained representations could serve many tasks through additional output layers. BERT paper Jev therefore belongs to a broader evolution toward specialized model interfaces, with an emphasis on runtime-defined questions, structured outputs, uncertainty, and efficient serving.
A useful comparison comes from JevLite, an independent implementation built on Qwen3-4B. Its researchers adapted the model to read probabilities over declared answer labels in a single forward pass. On their scam-call screening experiment, median decision latency was 64.5 milliseconds, compared with 317 milliseconds for a generative fine-tune using the same backbone—approximately a 4.9-fold difference.
The study covered 41 synthetic test scenarios and acknowledged test-set exposure during recipe selection. A trained ModernBERT encoder was faster still and was not significantly worse in accuracy. These findings show that the advantage depends on task and implementation, while supporting direct decision outputs as an efficient design choice. Open-Jev Judgments on CallScreenBench
The future will combine specialists
The strongest case for Jev is an application that uses it frequently and sends selected cases to a more capable model.
In JEV-as-a-Judge, researchers compared Jev with sixteen generative and reward-model judges. On ordinary preference and evidence-grounded factuality tasks, it performed within three percentage points of the strongest comparator at 0.36% of that comparator’s fee.
The researchers also evaluated a predefined cascade: accept confident Jev judgments and escalate uncertain ones. One configuration achieved 92.5% accuracy, compared with 93.1% for the stronger judge, at approximately 57% of its fee. These were offline simulations, and difficult adversarial examples required more escalation. JEV-as-a-Judge
The economics become attractive when a fast first stage resolves enough cases to reduce expensive downstream work. That principle has an established research foundation.
FrugalGPT, published in Transactions on Machine Learning Research, demonstrated that learned model cascades could match the best individual model with up to 98% lower cost on studied tasks. RouteLLM showed that trained routers could select between stronger and weaker language models while reducing cost and preserving response quality. FrugalGPT, RouteLLM
Jev extends this trajectory into a general interface for judgments inside software. A model can help determine which evidence matters, which handler fits a request, or whether further reasoning is justified.
What professional and Chinese-language tests reveal
Practitioner evaluations report useful gains at more modest scales than TypeSafe’s launch headlines.
AY Automate tested 791 labeled decisions against four LLMs. Jev was 2.0–3.6 times faster at the median and 4.7–7.5 times cheaper than the two cheapest small-model baselines. Its accuracy varied by task. A Jev-first cascade achieved accuracy comparable to the stronger baseline at approximately 26–28% of its cost, although those cascade estimates require further validation. AY Automate benchmark
Chinese-language firsthand reviews add practical examples. VerySmallWoods built a playground and tested five scenarios through Vercel AI Gateway. The author reported upstream latency of 210–340 milliseconds, with end-to-end times between 350 milliseconds and one second. A five-question support-triage example returned in approximately 245 milliseconds upstream, illustrating how several judgments can share a request. VerySmallWoods’ Chinese review
AwenDXB’s workflow experiments show why total system cost matters. A small comparison reported Jev at 362 milliseconds versus 922 milliseconds for DeepSeek, with approximately 1.8 times lower per-call cost. Filtering a document workload increased overall cost, while compressing conversation tool outputs reduced it by approximately 54%. AwenDXB’s Chinese evaluation
The implication is concrete: decision models create value when their judgments remove enough downstream work, improve routing, or enable behavior that was previously too slow or expensive.
Jev will improve through measurable engineering work
The current weaknesses define a clear development agenda.
Reliable probability estimates remain unfinished work. Just Ask Jev, a recent preprint covering 44 alignment-failure benchmarks, found strong ranking performance but inconsistent calibration across tasks. Its generic Noul questions reached median AUROC 0.886 on 31 applicable benchmarks, while decision thresholds needed adjustment. A model can rank cases effectively without assigning accurate absolute probabilities. Just Ask Jev
Research also demonstrates that calibration can improve. A paper published in Findings of ACL 2026 introduced calibration-aware reinforcement learning that preserved the studied accuracy levels while reducing expected calibration error by up to nine points. This is independent work, rather than a description of Jev’s proprietary training, but it establishes a route for progress. Calibration-aware reinforcement learning
Better diagnostics will matter alongside better training. Simon Willison identifies classification and reranking as useful fits for Jev, while raising the problem of opacity: a returned number does not explain which evidence drove the result. His review makes a persuasive case for structured experiments and evaluation. Willison’s review
Typed outputs solve an interface problem. Accuracy, calibration, robustness, and traceability remain separate targets for improvement.
The category is already taking shape
Independent implementations are emerging. JevLite demonstrates a task-specific approach using Qwen. SemIf reproduces the interface pattern with open models, reading option probabilities directly without generating an answer sentence. It explicitly distinguishes that implementation from Jev’s undisclosed model and training. SemIf project
This makes the direction larger than one company. Developers can pursue decision models as hosted services, local components, specialized encoders, or adapted language models. The appropriate implementation will depend on latency, task flexibility, calibration, and deployment requirements.
Jev will shape the future of generative AI by making judgment easier for software to consume. Its successors will improve the quality and efficiency of those judgments, while competing systems expand the available approaches.
Generative models will continue to create content and perform difficult reasoning. Decision models will increasingly coordinate when, where, and how those capabilities are used. That division of work will make AI applications faster, more economical, and more deliberate about spending computation.